plot_determinant_stack(
  captures = determinant_layers()$layer,
  title = 'Which rung first secures each layer')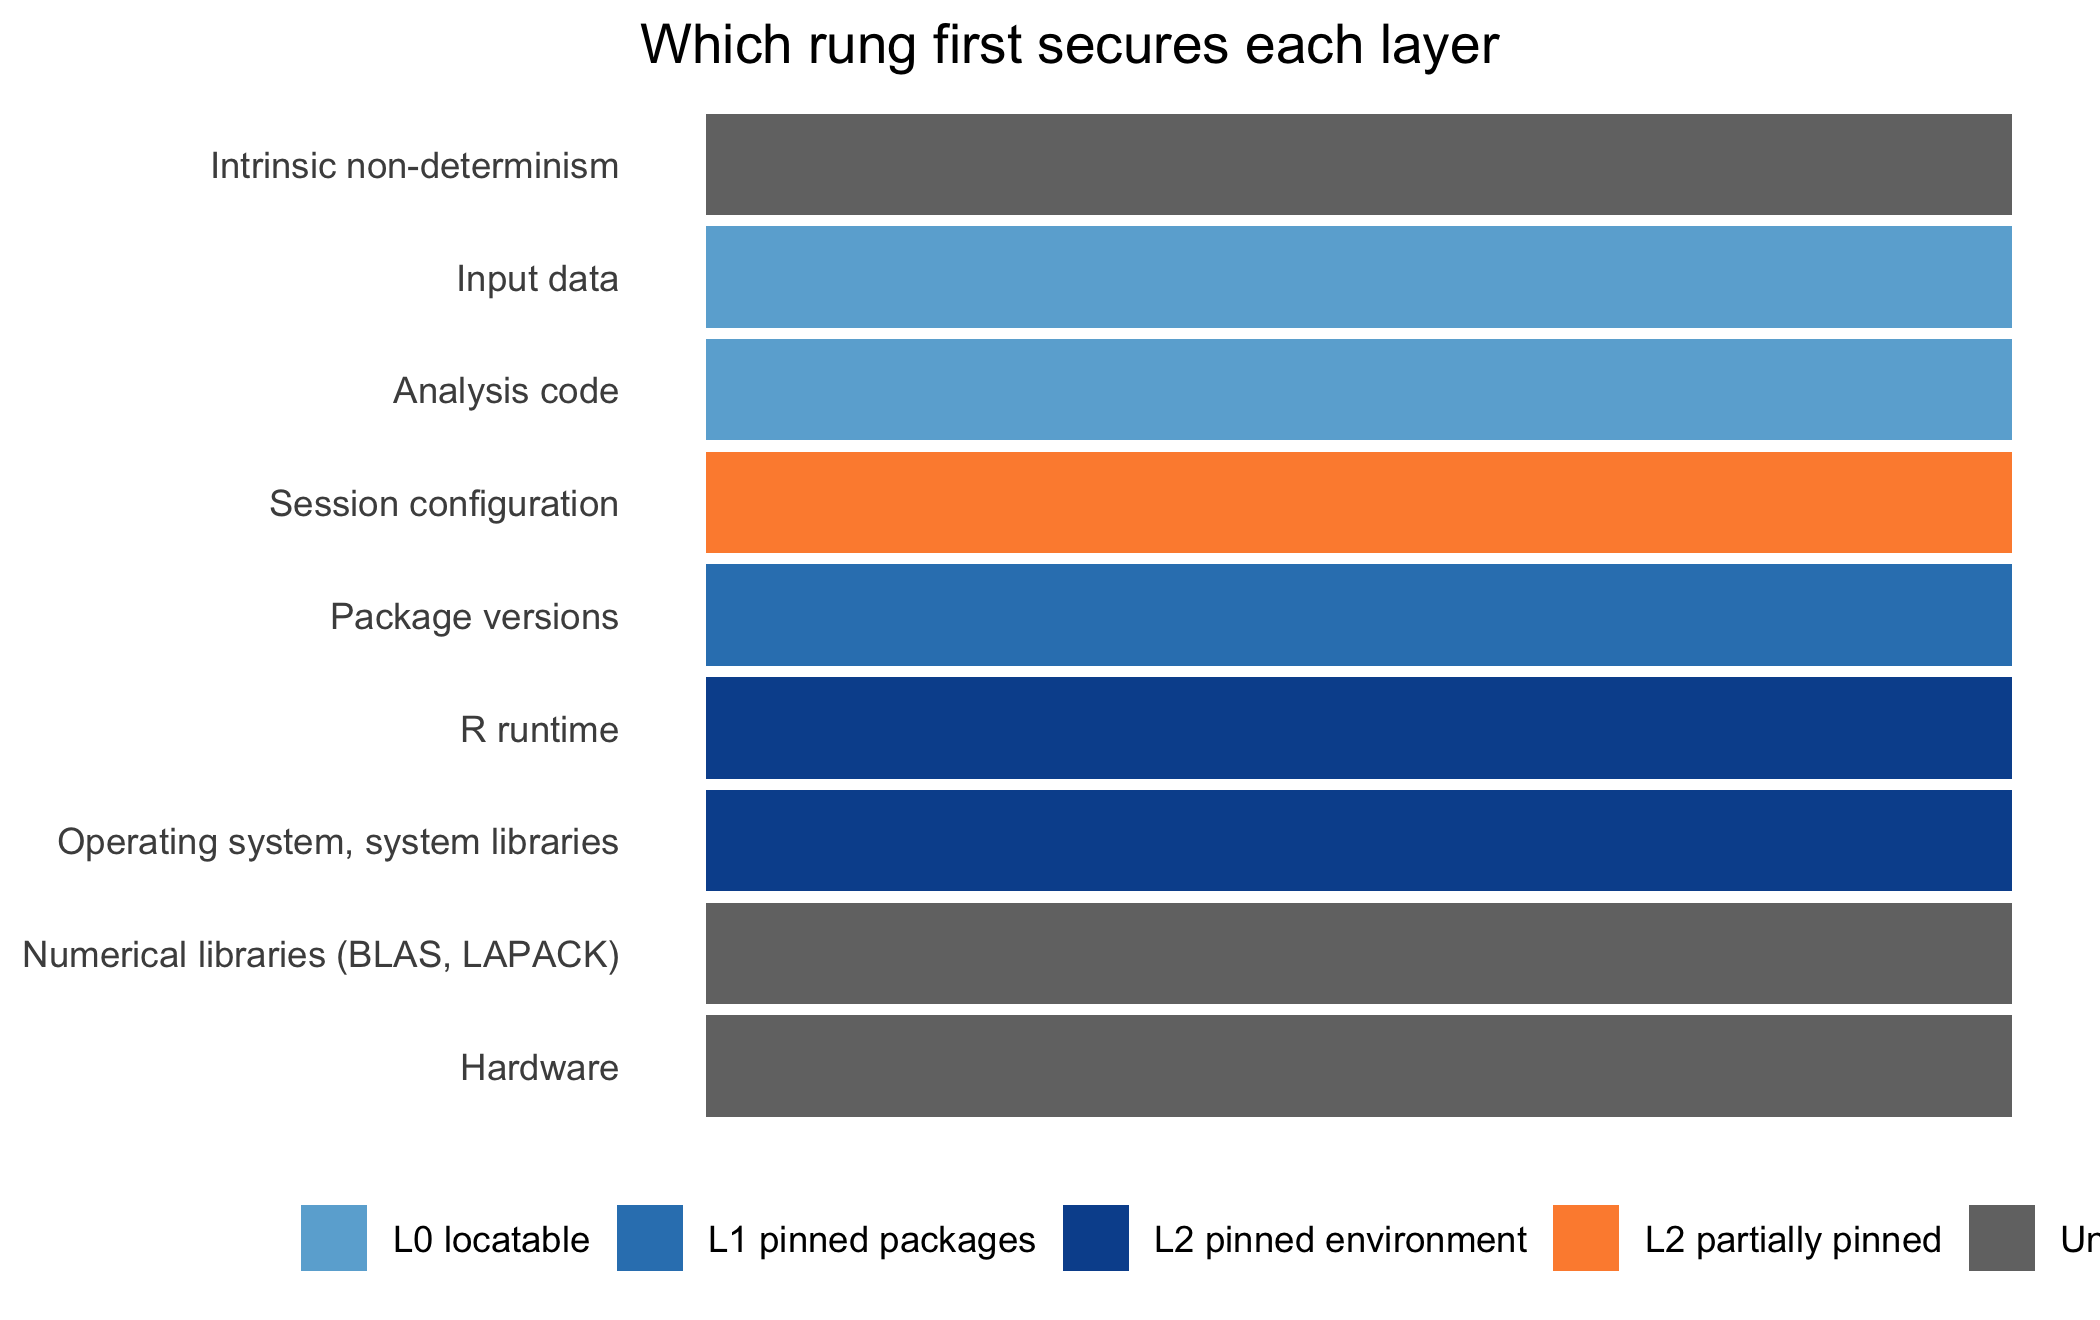
Reproducibility has the potential to serve as a minimum standard for judging scientific claims when full independent replication of a study is not possible.
Roger D. Peng, Reproducible Research in Computational Science (2011)
By the end of this chapter you will be able to look at any repository, your own or someone else’s, and say exactly which of four rungs it has reached. You will also be able to say what still stands between it and the next one, rather than reach for the unfalsifiable claim ‘fully reproducible.’
Consider a registry study of thirty-day readmission after heart failure. The analyst fits a mixed-effects model, draws a forest plot, and reports an adjusted odds ratio of 1.24. The script runs, the manuscript renders, the paper is accepted. Two years later a reader requests the code, downloads it, and runs it on a fresh laptop. The model fits, but differently. A package that the analysis relied upon has changed its default optimizer, and the estimate now returned is 1.19. Which number is the finding? The discrepancy is computational in origin. The model specified was the same on both machines; what differed was everything underneath it, and the analyst never recorded it. Its size, however, is a statistical finding. An estimate that moves from 1.24 to 1.19 when only the optimizer changes signals a flat or ill-conditioned likelihood, or a fit that has not converged. It should be checked, for example by refitting under several optimizers with lme4::allFit(), and reported as optimizer-sensitive.
This chapter is about naming that ‘everything underneath’, and about grading how much of it a given analysis has secured. We introduced in Chapter 1 the observation that a computational result depends on a stack of determinants beneath the code and the data, and that a published script pins almost none of them. Here we make that observation precise. After setting out the judgments that remain with the analyst, we shall lay out the stack layer by layer. We then define the ladder that this book uses to say how far down the stack a particular effort has reached: L0 locatable, L1 pinned packages, L2 pinned environment, and L3 verified. With the ladder in hand, we consider how the words ‘reproduced’ and ‘replicated’ have shifted across the literature, and how the framework’s own numbering differs from ours. Lastly, we examine how the ladder grades each archetype, admit that no framework pins the whole stack, walk one analysis up all four rungs, and then place this book’s own compendium on the ladder.
The ladder is the conceptual backbone of everything that follows. Every later chapter is, in effect, an account of how to climb one rung of it. Pinning packages with a lockfile (Chapter 6) is the L0-to-L1 step. Pinning the environment with a container (Chapter 7) is the L1-to-L2 step. And verifying the outputs (Chapter 12) is the L2-to-L3 step. Before we can teach the climbing we need the ladder itself, together with the discipline of naming, without flinching, the rung one has actually reached.
We begin with three judgments at the center of this chapter that belong to the analyst and are automated by no tool. The machinery of later chapters exists to support them.
Choosing, and declaring, the honest level. A framework can compute which rung a repository has reached and print it; it cannot decide what the author will claim. The judgment that a paper’s reproducibility statement will match the level actually secured, and never assert above it, is the analyst’s alone. It is the single habit this book most wishes to instill.
Matching the investment to the stakes. Climbing the ladder costs effort, and not every analysis warrants the climb. A two-day exploratory calculation may honestly rest at L0; a registry study destined for a guideline warrants L2 or L3. Deciding where on the ladder a given project should sit, given its lifespan, its audience, and the cost of being wrong, is a design decision.
Naming what remains exposed. No rung of the ladder pins the whole stack. The analyst who reaches L2 must still ask whether the layers left unpinned (the numerical libraries, the random-number discipline, the integrity of an external data source) matter for this particular analysis. Those that do must be closed by hand. Telling a live exposure from an inert one is a matter of subject-matter judgment.
New terms are defined again on first use; they are collected here for reference.
renv.lock, recording the exact version of every package an analysis used.RNGkind(). Two runs with the same seed but a different kind draw different numbers.We turn now to the determinants, because the ladder is only intelligible once we see what it grades. A computational result is the output of running some code against some data. However, the code and the data are only the two topmost of a tall stack of dependencies. The result is a function of the whole stack, not of its top two layers alone. Arranging the determinants from the hardware upward to the analysis logic yields the nine layers this book uses; a finer split, such as one that separates the document toolchain, yields ten or more.
At the base sits the hardware: the processor architecture, its instruction-set extensions, and the behavior of its floating-point unit. Above it lie the numerical libraries, the BLAS and LAPACK implementations that perform the linear algebra beneath every regression and every matrix decomposition. These matter more than their obscurity suggests. A different BLAS, or the same BLAS run with a different thread count, reorders the floating-point summations and can change a result in its low-order digits. Above these sit the operating system and its system libraries: the kernel, the C library, the locale data, the fonts, and the document toolchain of pandoc and LaTeX. Then comes the R runtime itself, whose default behaviors shift between releases. The random-number change of R 3.6.0 and the stringsAsFactors change of R 4.0.0 both illustrate the point.
Above the runtime sit the layers most analysts think of first. The package versions, the exact release of every R package the analysis loads, are the layer that churns fastest and breaks analyses most often. The session configuration is a cluster of settings that shape the session before any user code runs. It comprises the random-number kind set by RNGkind(), the contrasts used for factor variables, and the number of printed digits. It also comprises the locale that governs sorting, and the time zone that governs date arithmetic. Then come the two layers the analyst actually writes. These are the analysis code, including every set.seed() call and the order of execution, and the input data, its content and its integrity. Finally, threaded through the whole stack, sits intrinsic non-determinism: the use of the wall-clock, race conditions in parallel code, and iteration over unordered structures are each capable of producing a different answer on two runs of identical inputs.
Common practice pins very few of these layers. A bare published script pins exactly one layer with any reliability, the analysis code, since the code is the file itself. If the reader is fortunate, it pins a second, the data, when it has been deposited alongside. Every other layer is left to whatever the next machine happens to provide. Figure 3.1 maps the stack against the rung of the ladder that first secures each layer. Three layers (the hardware, the numerical libraries, and intrinsic non-determinism) are secured by no rung of the capture ladder at all. The numerical libraries are the case most often misread. A container image determines which BLAS is installed, but the ladder does not require that library to be fixed, and the thread count and the processor still vary between machines. No rung therefore guarantees this layer.
plot_determinant_stack(
captures = determinant_layers()$layer,
title = 'Which rung first secures each layer')Two settings of the session-configuration layer deserve a word, because they are the settings most often forgotten by an analyst who has already adopted a lockfile and a container. The random-number kind is the more dangerous. An analysis that seeds its generator and draws a sample is reproducible only if the algorithm behind the seed is also fixed. The change of the default sample.kind in R 3.6.0 broke exactly this, silently, for every analysis that had set a seed under the old default: the same seed now drew different samples, so no seeded result regenerated digit for digit. Whether a result also changed as a statistical matter is a separate question. Chapter 11 answers it on the book’s cohort (Table 11.2): the shift is a fraction of one Monte Carlo standard error, so the bound reproduces statistically although not seed-exactly. Given that simulation studies, multiple imputation, and bootstrap confidence intervals are staples of health research, the RNG kind is a first-order concern. The locale is the second. sort() and order() on a character vector depend on LC_COLLATE, so an analysis developed under one locale and re-run under another can reorder a table without any error. The decimal mark is a different matter. R keeps LC_NUMERIC at ‘C’ and warns if code changes it, so base parsing reads ‘.’ as the decimal mark whatever the system locale. A file written with decimal commas is read as text unless the reading function is told otherwise, for example with dec = ',' in read.csv().
The RNG kind also shows why a setting can belong to two layers at once. The R release sets the default kind, so the default is part of the R runtime and is fixed at L2. Code or a project .Rprofile can override the default, and an override is session configuration, fixed only by an explicit RNGkind() call in the analysis code. The same distinction between a default and an override recurs across the stack, and the table below states it for the settings this book returns to most often.
| Setting | What fixes the default | What can override it | What closes the override |
|---|---|---|---|
RNG kind (sample.kind) |
The R release (R runtime, L2) | Code, .Rprofile, a package |
An explicit RNGkind() call in the analysis |
stringsAsFactors |
The R release (R runtime, L2) | The argument in each call | Writing the argument in the code |
| Locale and time zone | The image or the host (L2 when the image sets them) |
Sys.setlocale(), Sys.setenv(TZ = )
|
Setting them in the image or in the analysis |
| BLAS and LAPACK | The image or the host (no rung) | The library path, the thread count | No rung; fixing the thread count narrows it, and a stated tolerance absorbs what remains |
With the stack in view we can define the ladder. The central design idea, which we take from the framework this book uses and develop as a general principle, is that the features acting on reproducibility divide into two kinds that are constantly confused. Separating them is what makes an honest grade possible.
The capture axes fix inputs, and therefore set the level. There are two of them: the package backend, which pins the package layer, and the computational environment, which pins the operating system, the runtime, and the system libraries. Adding a capture feature raises the level; removing one lowers it. The validation layer confirms the captured level without capturing anything new. Its members are continuous integration, the dependency-consistency check, and the output-verification command. Removing a validation feature leaves a repository exactly as reconstructable as before; it only stops the automated checking. This is why continuous integration, which we develop in Chapter 12, is best understood as the harness that runs the verification rather than as a layer of reproducibility in its own right. Pinning is capture; re-running to confirm is validation.
The four rungs follow from this distinction. Levels L0 through L2 are reached by the capture axes, and L3 is reached by the validation layer. Table 3.1 states each rung, what it pins, the artifact that marks it, and what the rung means for a reader of health research.
library(tibble)
library(knitr)

ladder <- tibble::tibble(
  Level = c('L0 locatable',
            'L1 pinned packages',
            'L2 pinned environment',
            'L3 verified'),
  `What is pinned` = c(
    'Nothing computational; the source is under version control',
    'The exact version of every R package',
    'The operating system, the R runtime, and the system libraries as well',
    'Nothing new; the recorded outputs are shown to regenerate within a stated tolerance from a clean rebuild'),
  `Primary artifact` = c(
    'A version-controlled repository',
    'A lockfile such as renv.lock',
    'A container image or a Nix environment',
    'A passing baseline test, run after a clean rebuild, that compares regenerated outputs with values recorded in a committed baseline file within a stated tolerance'),
  `Health-research reading` = c(
    'A reviewer can find the code but cannot yet rebuild it',
    'A colleague installs the same packages the analysis used',
    'The analysis yields the same numbers on a different machine',
    'The reported table has been shown to regenerate, not merely asserted to'))

knitr::kable(ladder)| Level | What is pinned | Primary artifact | Health-research reading |
|---|---|---|---|
| L0 locatable | Nothing computational; the source is under version control | A version-controlled repository | A reviewer can find the code but cannot yet rebuild it |
| L1 pinned packages | The exact version of every R package | A lockfile such as renv.lock | A colleague installs the same packages the analysis used |
| L2 pinned environment | The operating system, the R runtime, and the system libraries as well | A container image or a Nix environment | The analysis yields the same numbers on a different machine |
| L3 verified | Nothing new; the recorded outputs are shown to regenerate within a stated tolerance from a clean rebuild | A passing baseline test, run after a clean rebuild, that compares regenerated outputs with values recorded in a committed baseline file within a stated tolerance | The reported table has been shown to regenerate, not merely asserted to |
L3 is the one rung that cannot be read off a file listing. An analysis is at L3, verified, when its recorded outputs have been shown to regenerate within a stated tolerance from a clean rebuild. The showing is done by a baseline test, that is, a test that recomputes the reported quantities and compares them with values recorded in a committed baseline file. The comparison is made within a tolerance written into the test. A clean rebuild whose tests pass, but which compares nothing against a recorded baseline, demonstrates that the environment builds and the code runs. That is L2 confirmed, not L3. But why a tolerance, and not exact equality? Estimates are floating-point numbers, and exact equality would fail on harmless differences in the last digits while saying nothing about whether the substantive result moved. In the framework this book uses, zzc verify --full applies this definition. It records L3 only when the image rebuilds, the test suite passes, and at least one baseline test (a file named inst/tinytest/test-baseline*.R) exists and appears in the test log. Otherwise it reports the project as rebuilt and tested, L2, with no baseline comparison. Continuous integration that re-runs the check on every change keeps an L3 claim current. However, it is the baseline comparison, not the automation, that earns the rung.
The rungs are cumulative. An L2 analysis is also locatable and package-pinned; the label names the highest rung reached. The transition that matters most for a first-year student to internalize is the one between L1 and L2. A lockfile alone, the L1 artifact, pins the packages but not the R version, the operating system, or the system libraries a package links against. A lockfile restored under a different R version may fail to install or, more insidiously, may install and behave differently. The container image, the L2 artifact, fixes what the lockfile cannot. The two are complements, not substitutes, and a genuinely pinned-environment analysis carries both.
The ladder consolidates several graded views of reproducibility that the literature has offered in different vocabularies. Peng (2011) arranged computational work along a spectrum, from the merely published, through code available, code and data available, and linked and executable, to full replication. Our L0, L1, and L2 track the lower and middle reaches of that spectrum. The artifact-review badges used by the ACM and several computing venues express a related ordering, from artifacts that are available, through artifacts evaluated as functional and then reusable, to results independently reproduced (Association for Computing Machinery, 2020). The badges and the rungs grade different things and should not be equated. The ‘functional’ and ‘reusable’ badges grade how well an artifact is documented and exercised. They do not grade the package-versus-environment pinning depth that separates L1 from L2. Likewise, reaching L3 is not the same act as earning a venue’s reproduction badge, which is awarded by reviewers under that venue’s own policy. The reader who needs a badge should read the venue’s current definition directly. The L-scheme adds no new definition of reproducibility. It maps these graded views onto artifacts a tool can detect, so that the level of a repository can be determined mechanically and reported honestly, rather than asserted by its author.
The ladder grades re-execution, and re-execution is only one of the things the word ‘reproducibility’ is made to carry. We need to fix the terms before reading the literature, because the same two words are attached to opposite meanings across the sources a reader will meet.
The National Academies, in their 2019 consensus report, adopt the distinction this book follows (National Academies of Sciences, Engineering, and Medicine, 2019). Reproducibility is obtaining consistent computational results using the same input data, the same code, and the same conditions of analysis. That is, it is a statement about re-execution, and it is what the ladder grades. Replicability is obtaining consistent results across studies aimed at the same question, each with its own data. It is a statement about whether a scientific finding holds on new data. The two are independent. A result can be perfectly reproducible and entirely wrong, if the code faithfully regenerates a mistaken number every time. Conversely, a finding can replicate across laboratories while no single analysis in the set is computationally reproducible. Leek and Peng press exactly this point, that a reproducible analysis can still be wrong, and that reproducibility is therefore a floor and not a ceiling (Leek & Peng, 2015). Patil, Peng, and Leek go further and offer a statistical framing of the distinction. They cast replication as a question about the agreement of estimates across studies rather than about the re-running of code (Patil et al., 2016).
How do other vocabularies relate to this one? The current ACM artifact-badge vocabulary, in its 2020 revision, aligns its direction of use with the National Academies convention rather than inverting it (Association for Computing Machinery, 2020). However, the two draw the boundary differently. Under the National Academies convention, ‘Reproduced’ means obtaining a prior result using the same code and data; the same team re-running their own analysis qualifies. Under the ACM ‘Results Reproduced’ badge, the re-running must be done by a team other than the original authors, using the author’s provided artifacts. Both conventions therefore point ‘Reproduced’ toward re-execution with the original artifacts and ‘Replicated’ toward independence. The ACM badge, however, specifically requires a different team, while the National Academies definition does not.
The genuine word-swap that trips students belongs to two other places. One is the pre-2020 ACM badging, which attached the two words in the opposite direction along the re-execution axis. The other is a set of biomedical and other field-specific usages, which a reader may still encounter, where ‘reproduce’ names an independent study rather than a re-run. A reader who carries the sense of the words from one of those older documents into a current one will be misled. The misreading happens silently and without any error to warn them, in exactly the manner of a shifted package default. This book therefore fixes the meaning and states it once. Throughout, ‘reproduced’ carries the National Academies sense. L3 means that the captured analysis, rebuilt from its pinned definition and re-run, regenerates its own recorded outputs within a stated tolerance, as checked by a baseline test. It is deliberately not replication in the sense of an independent study on new data, which no software framework can supply. When the reader meets ‘reproduced’ or ‘replicated’ in a journal’s author instructions or a venue’s badging policy, the first task is to determine which convention that document uses.
This chapter uses ‘validation’ and the L3 label ‘verified’ for a narrow act: confirming that a previously captured value still holds, as a baseline test does. Regulated industry work, pharmaceutical and other FDA-adjacent settings among them, attaches ‘validation’ to something larger: a formal, documented process confirming that a system is fit for its intended use, as under 21 CFR 11.10(a) (21 CFR Part 11, n.d.). European regulators expect something comparable of a sponsor’s analysis tools (European Medicines Agency, GCP Inspectors Working Group, 2023). A graduate moving into that kind of work will meet the regulated sense on arrival; this book’s narrower one does not prepare them for the paperwork that comes with it.
This chapter defines the ladder rather than climbing it. Its one executed placement, the cohort compendium in ‘The cohort, continued’ below, is computed from the repository’s artifacts each time the chapter renders, not asserted here. Every rung above the one that section prints is left to the chapters this ladder points toward.
Before applying the ladder to particular archetypes, we need to dispose of a source of confusion. A reader who consults the documentation of the framework this book uses will encounter a second numbering scheme, and the two are easily confused.
The framework’s teaching materials include a vignette that presents a five-level ramp. Level 1 is a basic R project with manual package management, and Level 2 is the addition of renv. Level 3 is the addition of Docker, Level 4 the addition of unit testing, and Level 5 the addition of continuous integration. That scale counts which tools a project has adopted, and it is a pedagogical on-ramp, meant to be walked from the bottom as a project matures. It is a useful thing, but it is not the scale of this book.
The scale of this book is the architectural ladder of the preceding sections, L0 through L3. It grades something different: how far down the determinant stack a result has been locked, and whether the lock has been verified. The two axes are related but not identical. Adopting renv (the tool scheme’s Level 2) is what lifts a project to L1. Adopting a container (the tool scheme’s Level 3) is what lifts it to L2. The tool scheme’s testing and continuous-integration levels belong to the validation layer that reaches L3. However, one can imagine a project that has adopted every tool and still verified nothing. The architectural ladder, not the tool count, is what tells the reader whether the result has been shown to reproduce.
To avoid ambiguity we adopt a single convention. This book uses the L0 to L3 architectural ladder throughout, in every chapter and every worked example. Where the framework’s own documentation speaks of ‘Level 1’ through ‘Level 5’, it is using the tool-adoption ramp, and the reader should read it as such and not conflate it with our L0 to L3. When we write a bare ‘L2’, we always mean the architectural rung.
Does the ladder apply equally to every kind of compendium? Table 5.2 in Chapter 5 shows how each archetype reads it. A data-analysis project and a manuscript read it the same way. An R package reaches L2 by R CMD check and L3 by a baseline on its function outputs, and a blog applies the ladder post by post. The case most easily missed is the simulation study. Its exposure on the session-configuration layer is acute, because its outputs are functions of the random-number stream. An unseeded or wrongly seeded simulation can therefore sit at L2, with a perfectly pinned environment, and still fail to reproduce. For this archetype the discipline of fixing the RNG kind and the seed is the difference between a nominal L2 and a real one. The ladder is a property of the determinant stack, which every archetype shares, and not of any particular directory layout.
Reaching L2 or L3 does not pin the entire determinant stack, and no present framework pins all of it.
By its own published accounting, which splits the stack more finely than this chapter into about ten determinants, the framework this book uses robustly pins about four. These are the operating system and system libraries (as strongly as its base image is pinned), the R package versions (nominally, through the lockfile), the locale and time zone, and the source code. It leaves others to convention or to the base image. The random-number kind is not pinned by default. The BLAS and LAPACK implementation is inherited from the base image (the generated Dockerfile sets OMP_NUM_THREADS=1, which fixes the thread count but not the library). The integrity of external data is recorded by provenance but not by checksum, and the fonts and the graphics device are pinned only for some profiles. We know of no integrative framework that currently pins these layers, and an honest L2 or L3 claim names them. The reader will therefore find, at each rung of the ladder in the chapters ahead, an explicit account of what is secured and what remains exposed. That account includes the framework this book teaches.
To make the ladder concrete, consider a single analysis walked up all four rungs. A biostatistician has a folder containing analysis.R, which reads cohort.csv, fits a Cox model with the survival package, and writes a hazard ratio to results.csv. We shall place it on the ladder and name each transition.
At the start the folder is on the analyst’s laptop and nowhere else. It is at no rung of the ladder at all, because it cannot even be found by a second person. The first act, placing the folder under version control and pushing it to a repository, lifts it to L0, locatable. A reviewer can now find analysis.R and read it. Nothing computational is pinned; a reviewer who runs it will install whatever version of survival happens to be current, which may not be the version the analyst used.
The analyst now runs renv::init() and renv::snapshot(), which we develop in Chapter 6. This writes a renv.lock recording that the analysis used survival version 3.5-7, together with the exact version of every other package in the closure. The folder is now at L1, pinned packages. A colleague who restores from the lockfile obtains the same survival the analyst used. But the colleague’s laptop runs a newer R and a different operating system, and one of the packages links against a system library that is absent, so the restore fails to build.
To close that gap the analyst adds a container, developed in Chapter 7, built from a dated rocker base image pinned by its content digest. The image carries a fixed operating system, a fixed R, and the system libraries the packages need, and the lockfile restores inside it. The folder is now at L2, pinned environment. It will build the same environment on the colleague’s laptop, on a reviewer’s, and on a server. Because the analyst computes bootstrap confidence intervals for the hazard ratio, the analyst also sets the RNG kind with an explicit RNGkind() call in analysis.R, and passes a seed at the call that draws the resamples. Neither goes in the project .Rprofile. A seed set at session start makes every draw depend on whatever consumed random numbers earlier in the session, the rule Chapter 11 develops. This closes a session-configuration exposure that L2 does not close by default.
Finally the analyst adds a verification step, developed in Chapter 12. The step rebuilds the image from clean and re-runs analysis.R. It then runs a baseline test comparing the regenerated hazard ratio and its confidence limits with the values recorded in a committed baseline file, within a stated relative tolerance. It passes, and a continuous-integration service re-runs it on every change. The folder is now at L3, verified. That is, the reported hazard ratio has been shown to regenerate, not merely asserted to. The honest reproducibility statement for the paper can now name the rung, the artifacts, and the layers that remain outside the guarantee. No rung pins the hardware, the numerical libraries, or intrinsic non-determinism. For this analysis they amount chiefly to the cross-architecture numerical determinism of the bootstrap.
The worked example above follows a composite biostatistician. We now perform the same placement exercise on this book’s own running cohort compendium, as it stands in this repository when the chapter is rendered.
The extract loads and cleans without error, and clean_cohort() drops the one duplicated mrn the Conventions page describes, leaving the row count shown above. Whether the compendium is locatable, and whether anything beneath the code is pinned, is a question about which artifacts the repository holds, so we check rather than assert it.
repo_state <- c(
  source_code = file.exists('../../R/cohort.R'),
  data_generator = file.exists('../scripts/simulate_cohort.R'),
  lockfile = file.exists('../../renv.lock'),
  dockerfile = file.exists('../../Dockerfile')
)
repo_state
#>    source_code data_generator       lockfile     dockerfile
#>           TRUE           TRUE           TRUE          FALSE
rung <- if (repo_state[['lockfile']] && repo_state[['dockerfile']]) {
  'L2'
} else if (repo_state[['lockfile']]) {
  'L1'
} else {
  'L0'
}
rung_name <- c(
  L0 = 'locatable', L1 = 'pinned packages',
  L2 = 'pinned environment'
)[[rung]]
next_artifact <- c(
  L0 = 'a lockfile, `renv.lock`',
  L1 = 'a container recipe, a `Dockerfile`',
  L2 = 'a baseline test that passes after a clean rebuild'
)[[rung]]
The code is under version control, so a reader of this book can find R/cohort.R and read exactly what ran. The extract itself is not committed; the repository holds the generator, analysis/scripts/simulate_cohort.R, which writes the synthetic extract from a fixed seed. That much is L0, locatable. The lockfile entry above is TRUE and the Dockerfile entry is FALSE, so on its capture artifacts this compendium is at L1, pinned packages. What it still lacks for the next rung is a container recipe, a Dockerfile. Any layer that no present artifact pins is left to whatever R, system libraries, and packages happen to be installed on the machine that runs this chunk. The chapters on pinning packages (Chapter 6) and pinning the environment (Chapter 7) teach the artifacts that mark L1 and L2. The verification chapter (Chapter 12) is the one that can lift the compendium to L3, once a baseline test compares a quantity computed from cohort against a value recorded today; the chunk above does not look for one, so it never reports L3. The reader who returns to this cell after reading those later chapters is looking at the same lines of code. What changes, as artifacts are added, is the rung those lines print.
We turn finally to the use of a large language model, which is a capable assistant for reasoning about levels. However, it is confident in a register that this chapter has just taught the reader to distrust, and its confidence is not calibrated to the honest level.
One rule comes first (habit 3). Never paste or upload protected health information, identifiable records, or data held under a data use agreement, nor outputs derived from them, into a model or a coding agent unless three conditions all hold. The institution has approved that endpoint for that class of data. The IRB protocol and the consent permit the processing. The data use agreement, or the provider’s terms, permits it. If any of the three is unclear, the answer is no.
The third condition is the one most often missed. Institutional approval of a tool does not override the terms under which a data provider released the data. NIH, for example, treats sharing controlled-access data through prompts with public generative AI tools, which it glosses as third-party tools, as a breach of the data use certification. It treats a model trained on such data as a data derivative, to be shared only with other approved users and not kept after the project closes (National Institutes of Health, 2025).
Describe the structure instead: the column names and types, or a small synthetic example generated from the data dictionary, never edited from real rows. A coding agent sees whatever files are in its working tree, so run it in a checkout or container where the real data is not mounted.
An agent also acts, so confine it to a branch and keep merges, pushes, and deposits for yourself (Section 2.10.1).
A directory listing can itself be identifying when file names carry site or participant codes. List only the code, configuration, and lock files, and leave data directories out. The following triples illustrate productive prompts and the verification each demands.
Prompt. ‘Here is the listing of my project’s code and configuration files, with the data directories omitted. What reproducibility level has it reached on the L0 to L3 ladder, and what would it take to reach the next rung?’
Watch for. Reading a renv.lock as L1 and a Dockerfile as L2 is the right heuristic as far as it goes. However, no one can tell from a listing whether the lockfile is current, whether the image is pinned by a mutable tag or an immutable digest, or whether a verification run has ever passed. Check whether the answer reports L3 on the strength of a continuous-integration file that has never been run green.
Verification. Confirm each rung against the artifact itself, not its filename. For L1, check that the lockfile is in step with the code. For L2, check that the base image carries a digest and that the library is not shadowed by a bind mount. For L3, find an actual passing run of a baseline test after a clean rebuild, and read the test to confirm it compares outputs with recorded values under a stated tolerance. The presence of a file is capture asserted; a green baseline run is validation observed.
Prompt. ‘Below are the four rungs of a reproducibility ladder with their definitions, followed by a description of my project. Place the project on the ladder. For each rung, name the artifact in the description that meets its definition, or say what is missing. The rungs are cumulative. Say what you could not determine from the description.’
Supply the rows of Table 3.1 and the paragraph on cumulative rungs as the definitions, since a model cannot apply a scale it has not been given. Describe the project in prose: what is under version control, whether a lockfile exists, what the Dockerfile’s FROM line says, and what the tests compare.
Watch for. Check whether the answer applies the cumulative rule, or credits L2 to a Dockerfile in a project with no lockfile. Check whether it treats a base image named by tag as pinned in the same way as one named by digest. Check also whether it awards L3 to a test suite that compares nothing with a recorded baseline, which this chapter calls L2 confirmed, not L3.
Verification. Place the project yourself, from the artifacts, before reading the answer, and compare the two placements rung by rung. Then give the model a case whose answer you know, such as a project with a Dockerfile and no lockfile, and confirm that it does not award L2. A model that misplaces the known case should not be trusted on the unknown one.
Prompt. ‘My simulation gives slightly different numbers each time even inside the container. Why, and is it a bug?’
Watch for. Check whether the answer blames a layer that the container has already pinned, such as a package version or the operating system. Check also that it distinguishes an unseeded RNG (a real defect) from low-order-digit variation due to BLAS threading (an inherent limit at L2).
Verification. Trace the discrepancy to a layer of the determinant stack. If the numbers differ in all digits, look to the RNG kind and the seed, which the analyst controls. If they differ only in the low-order digits, suspect the numerical-library layer, which no rung of the capture ladder pins, and decide whether that residual matters for the inference at hand.
A better prompt. ‘My simulation, run twice in the same container, gives the two outputs pasted below. Also pasted are the sessionInfo() output, which names the BLAS and LAPACK libraries, the RNGkind() output, the line of my code that sets the seed, and the thread count. Say which layer of the determinant stack each difference most plausibly comes from, and for each give one command I can run to confirm or exclude it.’
For an analysis of your own, list the nine layers of the determinant stack and, for each, state whether your current setup pins it, and by what artifact. Identify the lowest layer you have left unpinned.
Take a published paper in your field that provides code. Without running it, place it on the L0 to L3 ladder from the materials the authors supply, and write the one-sentence reproducibility statement the paper should have carried.
Explain, to a colleague who believes that a Docker image makes an analysis ‘fully reproducible’, two determinants that the image does not pin and one circumstance in which each would cause two runs to disagree.
The framework’s documentation grades a project ‘Level 4’ on its five-level tool-adoption scale. State what this does and does not tell you about the project’s rung on the L0 to L3 architectural ladder, and name one artifact you would inspect to settle the question.
A colleague reports that a finding ‘replicated’ in a second cohort. A reviewer reads this as an ACM artifact badge and asks for the container. Explain the miscommunication in terms of the two conventions for the word, and state which sense the colleague almost certainly intended.
Construct a small simulation in R that draws a sample under a fixed seed, and show that changing the RNG kind with RNGkind() changes the draw while leaving the seed unchanged. Explain which layer of the determinant stack this demonstrates and why a container alone would not protect against it.
Run cohort <- clean_cohort(load_cohort('analysis/data/raw_data/cohort_raw.csv')) and report nrow(cohort). Then check file.exists() for renv.lock and Dockerfile at the project root, as the repo_state chunk in ‘The cohort, continued’ does. From that output alone, state the single rung of the L0 to L3 ladder this book’s own cohort compendium occupies, and name the one committed artifact, absent when you run the check, that would be needed to lift it to the next rung.
This exercise returns to the computational-versus-statistical distinction of Chapter 2 (Chapter 2). That chapter shows that the R 3.6.0 sampler correction changed the draws a seeded sample() call produces, with identical code and an identical seed. Name the exact layer of this chapter’s determinant stack responsible, and state which rung, if any, of the L0 to L3 ladder would have protected a 2018 analysis against this specific change.
Attempt an exercise before expanding its solution. Two of these ask you to work with an analysis or a paper of your own, so they have no single correct answer; for those the box says what a good answer establishes.
| Rung or rule | What it means or checks |
|---|---|
| L0 locatable | Source under version control; nothing computational pinned |
| L1 pinned packages | A lockfile (renv.lock) records every package’s exact version |
| L2 pinned environment | A container or Nix recipe also fixes the OS, R runtime, and system libraries |
| L3 verified | A baseline test compares regenerated outputs with recorded values, within a stated tolerance, after a clean rebuild |
| Capture vs. validation | Capture (a lockfile, a container) sets L0 to L2; validation (CI, a baseline test) adds nothing pinned, confirms the captured level, and is what reaches L3 (habit 5) |
| Reproduced (this book) | Same code, same data, re-run; contrast replicated: a new study, new data |
zzc verify --full |
Reports L3 only if the image rebuilds, tests pass, and a test-baseline*.R file appears in the test log |
| Honest statement | Name the rung, the artifact, and what remains exposed; never claim ‘fully reproducible’ (motto) |