plot_determinant_stack(
  validates = c('Analysis code'),
  title = 'A sealed render validates that prose and code agree; it captures nothing new')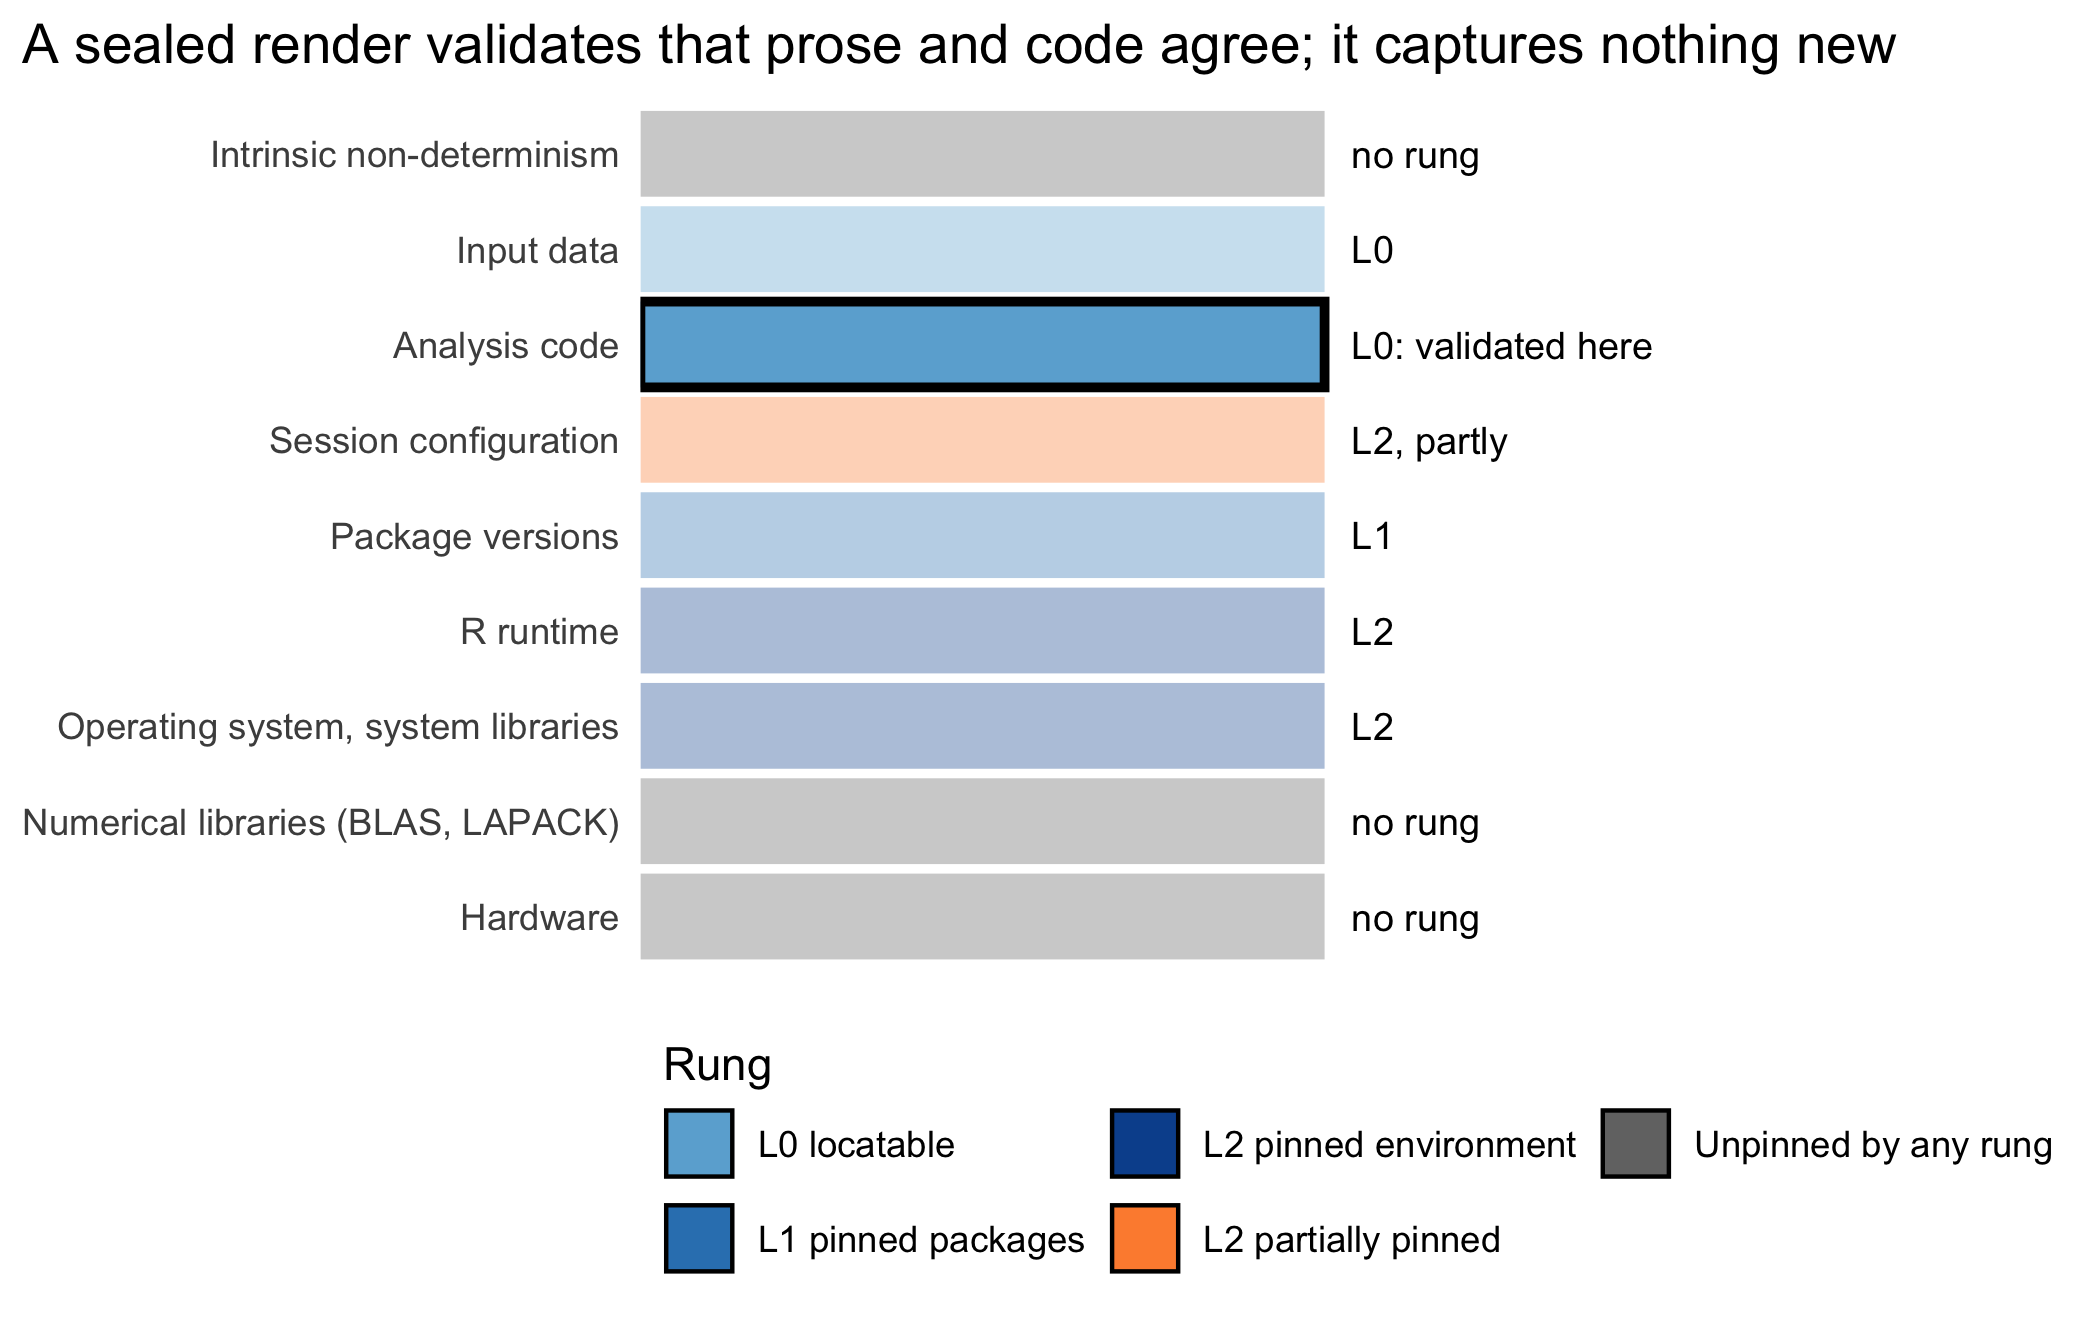
Let us change our traditional attitude to the construction of programs: Instead of imagining that our main task is to instruct a computer what to do, let us concentrate rather on explaining to human beings what we want a computer to do.
Donald E. Knuth, Literate Programming (1984)
This chapter has three aims. The first is to write an analysis whose every reported number and figure is produced by the code sitting beside it. The second is to recognize the handful of ways that guarantee silently breaks. The third is to say precisely what a successful render does and does not establish about an analysis’s place on the reproducibility ladder.
A sealed render is an unusual case among this book’s chapters, in that it pins nothing new. Figure 9.1 marks analysis code as validated here rather than captured, because version control already secures the code at L0. What a sealed render adds is the check that the document’s prose and figures are actually produced by that code, not pasted in and left to drift.
plot_determinant_stack(
validates = c('Analysis code'),
title = 'A sealed render validates that prose and code agree; it captures nothing new')Consider a familiar scene from a clinical-trial analysis. The statistician has a results table in the manuscript, produced months ago. She also has a script that, re-run today, produces a subtly different table: a mean that has moved in the third decimal, a confidence interval that no longer matches the sentence that interprets it. Neither the prose nor the code is obviously wrong. What has failed is the correspondence between them. The number in the paragraph was copied, by hand, from an analysis that has since been edited, and the paragraph was never updated. The document and its analysis have drifted apart, silently, and no one noticed until a reviewer asked how the interval was computed.
This chapter is about closing that particular gap, the gap between the prose a reader sees and the code that produced the numbers in it. The instrument is literate programming, by which we mean the practice of writing the narrative and the computation in a single source document. The figures and numbers a reader sees are then not pasted in but regenerated every time the document is built. We shall call a document with this property a sealed render: prose bound to the code that produces every number and figure it reports, so that the document cannot silently disagree with its own analysis.
The reader will recall the ladder of reproducibility levels that organizes this book: L0 locatable, L1 pinned packages, L2 pinned environment, L3 verified. But where on that ladder does a sealed render sit? The answer tends to surprise newcomers. A sealed render is, on its own, a property almost orthogonal to the ladder. It guarantees that the document agrees with the code, but it says nothing about whether the packages are pinned, whether the environment is fixed, or whether the outputs have been verified. One can have a beautifully sealed document that runs only on its author’s laptop, at L0. One can equally have a fully pinned L2 environment whose report pastes its numbers in by hand. The seal and the pins are different virtues, and much of the discipline of this chapter lies in not confusing them.
That said, the sealed render is the natural home for the machinery of the earlier chapters. It is where the pinned packages of Chapter 6 and the pinned environment of Chapter 7 are actually exercised, because it is the thing that runs the code. It is also the artifact that continuous integration renders on every change, as we shall see in Chapter 12. The sealed render is therefore the hinge between capturing an environment and validating that the capture suffices.
Three judgments in this chapter are the analyst’s own, and no tool makes them.
Deciding what the document computes at build time and what it merely loads. A figure regenerated on every render cannot drift from the text, which argues for computing everything in the document. A model that takes an hour to fit cannot be re-fitted on every render, which argues for computing it once in a script and caching the result. Where to draw this line is a design decision the analyst makes for each project. The line falls between the code that lives in the sealed document and the code that lives in analysis/scripts/ with its output saved to derived_data/. The choice trades the strength of the seal against the cost of the render.
Keeping the render sealed by refusing to reach outside it. A sealed render must draw only on what is captured and committed. The temptations to reach outside are many and quiet, and we catalog them below as landmines. They are installing a package at render time, loading with pacman::p_load, reading a file by its absolute path on the author’s machine, depending on state left in the session by a previous chunk, reading a file that was never committed. Each produces a document that renders perfectly for its author and fails for everyone else. No linter catches all of them; the discipline is the analyst’s.
Matching the claim to what the render actually seals. A sealed render seals prose to code. It does not, by itself, seal code to its dependencies, nor dependencies to an environment, nor establish that the outputs are correct. The analyst who says ‘the analysis is reproducible’ because the report renders has claimed more than the seal delivers. The honest claim names the level actually reached, and we return to this below.
knitr or the Quarto engine to run the code, pandoc to convert the result, and, for PDF, a LaTeX distribution to typeset it.SOURCE_DATE_EPOCH. A conventional environment variable, honored by many document tools, that fixes the timestamp a build embeds, so that two builds do not differ merely because they ran at different moments.The idea is Knuth’s, and it is nearly as old as the practice of scientific computing itself. In 1984 Knuth proposed that a program should be written as a work of literature, a connected narrative addressed to a human reader, from which the machine-executable code is extracted mechanically (Knuth, 1984). He called the practice literate programming, and inverted the usual priority: the explanation is primary and the code is embedded within it, rather than the code being primary and the comments an afterthought. Knuth’s own motive was the comprehensibility of programs. The application to reproducible research came later, and from a different quarter.
That application, and the sentence this book takes as its keystone, is due to Buckheit and Donoho, writing in 1995 about their WaveLab software and paraphrasing their colleague Jon Claerbout (Buckheit & Donoho, 1995). Their argument, in its clearest form, is this. An article about computational science is not the scholarship itself; it is merely advertising of the scholarship. The actual scholarship is the complete software environment and the complete set of instructions that generated the figures. On this view the printed figures and tables are not the result but a picture of the result, and a picture can be a faithful likeness or a flattering one. The result itself, the thing that can be checked and built upon, is the code and the instructions that produce the figures. A paper that advertises a result it cannot regenerate has, in Claerbout’s sense, advertised scholarship it does not possess.
Literate programming is the technique that closes the distance between the advertisement and the scholarship. If the figure in the paper is generated, at build time, by code that lives in the same document as the prose around it, then the advertisement and the scholarship are the same artifact. The figure cannot be a flattering likeness of a result the code does not produce, because the figure is the output of the code. This is the whole of the reproducibility argument for literate programming, and every practical detail in the rest of this chapter is in service of it.
The R ecosystem has realized Knuth’s idea four times over, each realization improving on the last. The reader will meet all four in existing code, so we review the lineage briefly.
The first was Sweave, introduced by Friedrich Leisch around 2002 and shipped with R itself. Sweave let an author interleave R code with LaTeX prose in a single .Rnw file, ran the code, and wove the results into a LaTeX document. It proved the concept for R and served for a decade, but it was tied to LaTeX, awkward to extend, and offered little control over how code and output were formatted.
The second, and the decisive advance, was knitr, written by Yihui Xie and released in 2012 (Xie, 2015). knitr generalized Sweave in two directions at once. It decoupled the computation from the output format, so that the same code chunks could be woven into LaTeX, into HTML, or into Markdown. And it gave the author fine control over each chunk through chunk options, the echo, eval, warning, and fig.cap settings that recur throughout this book. knitr is still the engine underneath most R literate documents, including the executable chunk later in this chapter.
The third was R Markdown, which paired knitr with pandoc, the universal document converter (Xie et al., 2018). The author now wrote in Markdown, a light and readable prose syntax, rather than in LaTeX. pandoc then converted the woven Markdown into whatever final format was wanted: HTML for the web, PDF by way of LaTeX, Word for a collaborator who redlines in track changes. This is the report.Rmd that the zzcollab templates scaffold, and the format in which a great deal of current health-sciences analysis is written.
The fourth and most recent is Quarto, released by Posit in 2022 and documented by Allaire and colleagues (Allaire et al., 2024). Quarto is best understood not as a replacement for R Markdown but as its generalization beyond R. It keeps the knitr engine as one option and adds a Jupyter engine for Python and Julia. It also unifies the chunk-option syntax across languages into the #| comment form used in this book, and it standardizes the production of books, websites, and journal articles from the same source. This very book is a Quarto book. For an R analyst the migration from R Markdown to Quarto is small, and the two will coexist for years. All four tools implement the same idea, and any of them can secure the seal.
We begin with a figure. The following chunk generates a small synthetic dataset in the spirit of the Palmer penguins, three species measured on two bill dimensions. It fits a within-species and a pooled relationship, and draws the result. The point of the exercise is not the statistics, which are a textbook instance of Simpson’s paradox, but the mechanism: this figure is produced when the book is built, from the code the reader sees, and it cannot therefore disagree with the sentences around it.
library(dplyr)
library(tibble)
library(ggplot2)

set.seed(2024)

make_species <- function(name, mean_length, base_depth,
                         n = 60) {
  bill_length <- rnorm(n, mean = mean_length, sd = 2.2)
  bill_depth <- base_depth +
    0.15 * (bill_length - mean_length) +
    rnorm(n, sd = 0.6)
  tibble(species = name,
         bill_length = bill_length,
         bill_depth = bill_depth)
}

penguin_like <- bind_rows(
  make_species('Species A', mean_length = 39,
               base_depth = 18.5),
  make_species('Species B', mean_length = 49,
               base_depth = 18.5),
  make_species('Species C', mean_length = 47,
               base_depth = 15.0)
)

ggplot(penguin_like,
       aes(bill_length, bill_depth)) +
  geom_point(aes(colour = species), alpha = 0.7) +
  geom_smooth(aes(colour = species), method = 'lm',
              se = FALSE) +
  geom_smooth(method = 'lm', se = FALSE,
              colour = 'black', linetype = 'dashed') +
  labs(x = 'Bill length (mm)',
       y = 'Bill depth (mm)',
       colour = 'Species') +
  theme_minimal()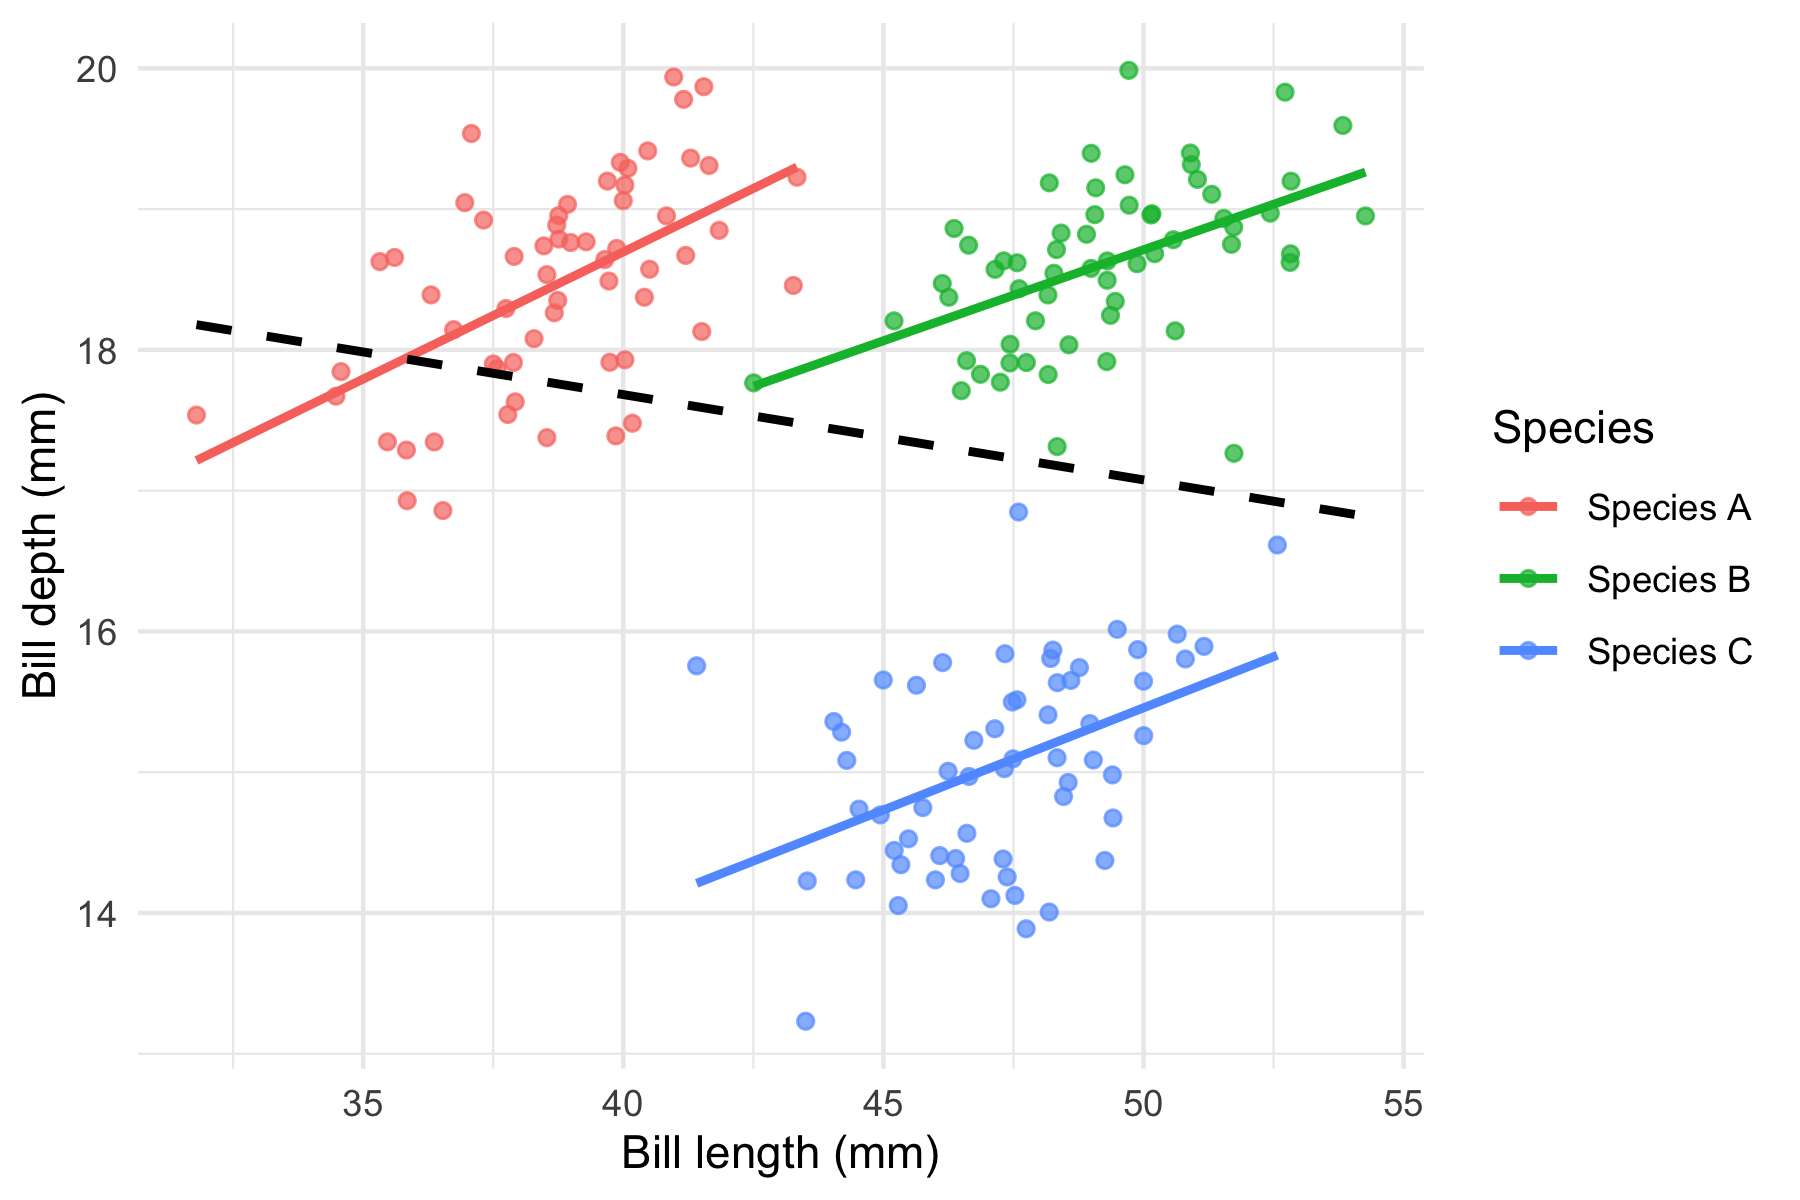
Within each of the three synthetic species, bill depth rises with bill length: the three solid lines slope upward. Pooled across the species, the relationship reverses sign. The dashed line comes out nearly flat with a slight downward tilt rather than a steep descent, because across species longer bills are associated on average with shallower ones. The reversal here is real but modest: it is the sign of the pooled slope that flips, not its magnitude that grows. This is Simpson’s paradox, and it is a useful thing for a figure to show. What matters more for this chapter is that the preceding paragraph is safe to write. If a later edit changed the synthetic means so that the pooled line no longer reversed, the figure would change on the next render. The paragraph would then become visibly false, prompting its correction. In a document that pasted the figure in as a static image, the paragraph could go on asserting a reversal the data no longer showed, indefinitely. The seal is precisely this coupling: the prose and the picture rise and fall together because they are the same computation.
Two properties of the chunk keep it sealed. First, it draws its data from set.seed() and rnorm(), not from a file on the author’s disk, so it carries its inputs with it. Second, it loads only packages that the build environment is known to provide, and installs nothing. A chunk that violated either property might still render on the author’s machine and would fail on anyone else’s. The next section is a catalog of exactly these violations.
A figure is the conspicuous case, and the inconspicuous one does more damage. Numbers reported in prose are where drift is hardest to see, because a wrong number in a sentence looks exactly like a right one.
Having computed those, the sentence that reports them can be written with the values substituted rather than typed. In the laser-treated arm of the retinopathy trial there are 197 eyes, of which 54 progressed to visual loss, a rate of 27.4 percent.
If we read the source of that sentence, we find no numerals in it. Each is an inline expression evaluated at build time, so if the trial data were corrected, or the arm redefined, the sentence would change with it. This is the same seal the figure has, applied to the unit of text where a reader is least able to detect a lie. It is also the cheapest reproducibility discipline in this book: it costs a few characters per number, and it removes an entire class of error that no test, no lockfile, and no container can reach.
The habit generalizes. Any number a reader might check against the analysis, a sample size, a count of exclusions, a rate, a p-value, belongs in an inline expression. Numbers that are genuinely constants of the study design, an enrollment target or a protocol threshold, are properly typed, because they are inputs rather than results.
A sealed render is fragile in a specific way: it holds only if everything the render touches is captured and committed. Several common patterns reach outside that boundary, and each produces the same failure signature, a document that renders flawlessly for its author and errors, or worse renders differently, for a later reader. The zzcollab publishing playbook calls these landmines, and the name is apt, because they lie undetonated in a document that works until the moment someone else steps on it. We take the principal ones in turn.
The first is installing packages at render time. A chunk that calls install.packages('somepkg') or pak::pak('somepkg') during the render reaches out to a package repository as it builds. This makes the render depend on network access, on the repository’s state on the day of the render, and on whatever version is current then. The remedy is that provisioning belongs in the environment, the Dockerfile and the lockfile of the earlier chapters, never on the render path. A sealed render installs nothing; it assumes its packages are already present, pinned, and captured.
The second, a specific and common case of the first, is loading with pacman::p_load. The pacman package offers p_load(), which installs a package if it is missing and then loads it, in one call. It is convenient in interactive exploration and a liability in a sealed render. On any machine where a named package is absent, it installs whatever version the repository serves that day, with all the fragility just described, and the render then succeeds against a package set no one chose. It also makes pacman itself a silent dependency of the render. On a machine without pacman, the call stops at once with ‘there is no package called ’pacman’’. A common belief is that dependency scanners cannot see the packages p_load() names, but renv can. In a test with renv 1.2.3, renv::dependencies() reported the packages passed to p_load() as well as pacman itself, and the solution to Exercise 8 repeats the scan at every build. A scanner built on a narrower search may not, so whether a given scanner sees them is a question to test, not to assume. The remedy is to replace pacman::p_load(a, b, c) with explicit library(a), library(b), library(c) calls. These name the dependencies in the form every scanner recognizes, and they load without installing.
The third is absolute host paths. A chunk that reads /Users/jsmith/data/cohort.csv, or sources a LaTeX preamble from ~/shr/preamble.tex, embeds a fact about one particular machine into the document. The path exists on the author’s laptop and nowhere else, so the render fails the moment the document moves into a container, onto a colleague’s machine, or into continuous integration. The remedy is that every file a render touches must live inside the compendium and be referenced by a relative path, so that the document carries its inputs with it.
The fourth is hidden state. A document renders its chunks in order, in a single R session. In that setting it is easy to write a chunk that depends on an object created in an earlier chunk, or on an option set earlier, or on a package attached earlier, without saying so. The document renders correctly from top to bottom and fails when a reader runs the chunk in isolation, or when a chunk is reordered, or when caching skips the chunk that created the state. A related anti-pattern is a chunk that calls rm(list = ls()) to force a clean slate. It does not actually deliver one, since attached packages and changed options survive it, and it can delete objects the rendering harness itself relies on. The remedy is a discipline of self-contained chunks and, at the level of the toolchain, rendering each document in a fresh session so that no state leaks in from the author’s console.
The fifth is reading uncommitted files. A chunk may read a file that exists in the author’s working directory but was never committed to version control, a scratch CSV, a manually downloaded spreadsheet, an intermediate the author produced by hand. The render succeeds for the author, whose working tree contains the file, and fails for anyone who clones the repository, whose working tree does not. This is the subtlest landmine, because version control hides it: the document and the file both sit in the author’s directory, and only a clean checkout reveals that one of them was never tracked. The remedy is that a sealed render reads only committed inputs, and the surest test is to render from a fresh clone.
Every landmine in this section shares one signature: the render succeeds on the author’s machine. Local success is therefore no evidence that a render is sealed. The only convincing test is a render in a clean environment that carries none of the author’s accumulated state, which is exactly what a container, or continuous integration, provides. We develop that test in Chapter 12; for now, the reader should treat ‘it renders for me’ as the beginning of the question, not the end.
Two features let a render skip work, and both weaken the seal without saying so on the page. Quarto’s freeze option acts on whole documents during a project render. With freeze: true a document is never re-executed by a project render. With freeze: auto it is re-executed only when its source file changes. Otherwise Quarto reuses the results stored in the project’s _freeze/ directory, and its documentation advises committing that directory, so that others can render the project without the environment that computed it (Posit Software, PBC, n.d.). Freeze applies only to a render of the whole project; rendering a single document always executes its code. The knitr chunk cache acts on single chunks. It saves the objects a chunk creates, its printed results, and the random seed, and reloads them on the next render. A change to the chunk’s code or options invalidates it (Posit Software, PBC, n.d.; Xie, 2011).
Neither feature looks at the rest of the stack. Under freeze: auto the comparison is with the document’s own source. A corrected data file, an updated package, a new R release, or an edited function under R/ therefore leaves the frozen results in place. The chunk cache behaves the same way unless the analyst ties it to those inputs, for example by setting the cache.extra option to the R version string or to a data file’s modification time (Xie, 2011). A cached chunk also skips its side effects, which is how caching springs the hidden-state landmine above. In each case the page carries a fresh build date over numbers computed earlier, perhaps on another machine.
This book is a case in point. Its _quarto.yml sets freeze: auto. When this page last executed, the repository committed frozen results for 15 documents (52 files under _freeze/). Its continuous-integration workflow runs a project render, so freeze applies there too. A chapter whose source has not changed since its last local execution is published with the results computed on the machine that executed it and committed _freeze/, not with results computed in the CI environment. The counts in this paragraph are subject to the same rule: they are as of this page’s last execution. For a book whose chunks illustrate rather than report, that trade may be acceptable. For a deposited analysis it is not. The render that produces a submitted or deposited document should run in the pinned environment with freeze off, or after deleting _freeze/ and the cache directories. Freeze and cache are conveniences for drafting, not evidence that the numbers are current.
A literate source document is format-agnostic; the same report.Rmd can render to HTML, to PDF, or to Word. The choice of format is not merely cosmetic, however, because each format invokes a different toolchain behind the render, and the environment must carry whatever the chosen format needs.
HTML is the lighter of the two. Rendering to HTML runs the code with knitr and converts the result with pandoc, and both are modest, self-contained dependencies. HTML is the natural default for a working analysis, for a blog post, and for anything read on a screen; it supports interactive figures, it degrades gracefully, and it imposes the smallest environmental burden. For most of a project’s life, and for every archetype whose output is read rather than submitted, HTML is the sensible target.
PDF is heavier, because a PDF is typeset, and typesetting in this ecosystem means LaTeX. Rendering to PDF runs the same knitr and pandoc steps and then hands the result to a LaTeX distribution. The distribution lays out the pages, resolves the cross-references, sets the mathematics, and embeds the fonts. A LaTeX distribution is large: a full TeX Live installation occupies several gigabytes. Its absence is the single most common cause of a PDF render failing on a machine where the HTML render succeeds. This is precisely the environmental problem the earlier chapters solved, and it is why the framework’s publishing profile exists.
The publishing profile builds on the rocker/verse base image, which carries a base LaTeX distribution sufficient for a straightforward render: plain prose, ordinary tables, standard mathematics. It does not carry a full LaTeX distribution. A document that reaches for a package the base omits (dense tables, moderncv-style layouts, and similar) still needs that package installed with tlmgr before it will render. zzcollab’s own publishing profile pre-installs roughly two dozen such packages at image build time precisely because the base image does not ship them. A project that renders to PDF chooses the publishing profile at initialization. A project that renders only to HTML does not need it, and pays neither the build time nor the image size that the LaTeX toolchain costs. The playbook that migrates a compendium to the publishing profile turns on exactly this question. It scans every report’s YAML for a pdf_document or latex_engine output and, finding one, concludes that the verse base is required.
As elsewhere in the book, the literate document declares what it wants to be, and the environment must be provisioned to supply it. HTML asks little; PDF asks for LaTeX. The honest way to supply LaTeX is to pin it in the image, not to install it, fragilely and at render time, on whatever machine happens to build the document.
The next point surprises many analysts, and it shapes how verification is done in Chapter 12. It is natural to suppose that the way to check a reproducible report is to render it twice and compare the two output files: if the analysis is reproducible, surely the PDFs should be identical? They will not be, and the reason is instructive.
A rendered PDF, and to a lesser degree a rendered HTML file, embeds metadata that has nothing to do with the analysis and everything to do with the moment of the render. A PDF carries a creation timestamp and a modification timestamp in its metadata. It also carries an internal document identifier, which engines derive from the time, the file name, and in some cases the build path. Some engines also give the font subsets they embed names that can vary between builds. Two renders of byte-for-byte identical source, in the same environment, minutes apart, therefore produce two PDF files that differ in their bytes. They differ even though every number and figure in them is identical.
Part of this non-determinism can be normalized away. Many document tools, including LaTeX and pandoc, honor a conventional environment variable, SOURCE_DATE_EPOCH, which fixes the timestamp the build embeds to a specified value instead of the wall-clock time. In a test with TeX Live 2026, setting it alone made two pdfLaTeX, XeLaTeX, or LuaLaTeX builds of a short document in one directory identical. Builds in different directories could still differ in their identifier, and a full report adds figures, paths, and tool versions, each another source of difference. Normalizing them all is worthwhile work in some settings, notably in the reproducible-builds movement for operating systems. For a research compendium it is usually misplaced effort, because it fights a symptom.
The resolution the framework adopts is to compare the right thing. Verification, developed in Chapter 12, does not hash the rendered document. It recomputes the computational outputs, the derived datasets, the model estimates, the figure data, the numbers themselves, and compares them with a recorded baseline within a stated tolerance (habit 5). The tolerance matters because even these numbers can move in their last digits under a different numerical library without the analysis changing. A hash detects any change at all, so it is the right instrument only for a file whose bytes should not change, such as a raw data extract; Chapter 12 develops both. The rendered report is a human-facing artifact, a faithful presentation of those outputs. It is checked by regenerating it and confirming that the outputs it presents match the recorded baseline within that tolerance, not by demanding that its bytes be identical. For provenance the framework goes further in the opposite direction. Its render hook deliberately stamps each rendered PDF with the render time and the source path, in a footer, and stages a dated copy whose name and manifest row record the git version of the source. A reader can therefore tell two renders apart and trace each to its source commit. The rendered document is thus a dated, signed presentation of a result; the object of record is the computation.
This chapter’s own executed chunks, fig-simpson, the inline-sealed retinopathy sentence, and the cohort passage below, are sealed. Every number in them regenerates from the code beside it. The seal adds no rung, however. These chunks sit on whatever rung the compendium’s lockfile and environment reach, which Chapter 6 and Chapter 7 compute from the repository; nothing in this chapter raises it.
The weight the sealed render carries varies sharply across the five archetypes; Table 5.2 in Chapter 5 is the reference. It is the center of gravity for the manuscript, multiplied across many posts for the blog, and lighter for an internal data-analysis summary. The two cases most worth stating here are the ones a reader fixed on the manuscript will misjudge. The R-package archetype has no sealed report at all. Its ‘document’ is its help pages and vignettes, generated from roxygen comments and demonstrating the package rather than reporting an analysis. Its correctness rests on the tests of Chapter 11, not on a rendered result. The simulation-study archetype inverts the usual weight for a different reason. The heavy computation, hours or days of Monte Carlo replicates, cannot live in the sealed document. It therefore runs once in analysis/scripts/, seeded with the care Chapter 3 stressed, and saves its results to derived_data/. The literate report then becomes a thin presentation layer that loads and presents those results. In every case the underlying machinery (knitr or Quarto, chunks, committed inputs, a pinned environment) is the same; only how heavily an archetype leans on it changes.
One matter of practice remains, and experienced compendium authors are most insistent about it. The traditional order of work runs: write the analysis scripts, generate the results, then start the manuscript, and finally copy the results into the prose. This order builds the drift we opened the chapter with directly into the workflow, because the copying is manual and the results and the prose are separate artifacts from the start.
The write-as-you-go doctrine inverts the order. We create the report.Rmd on the first day of the project, before there is any analysis to report. Into it we write the research question, the background, and the planned methods as prose. The analysis code is then added inline, in chunks, as the work proceeds, so that from the first day the numbers in the document are computed rather than copied. As patterns emerge, code that is used more than once is extracted from the document into a function in R/, and as those functions stabilize they acquire tests in inst/tinytest/, the subject of Chapter 11. When a computation grows too slow to run on every render, it moves to analysis/scripts/, is run once, and saves its result for the document to load. This is the build-time-versus-load-time boundary named among the analyst’s contributions above. The compendium’s directory structure, in this view, emerges from the writing rather than preceding it. That is, the manuscript drives the analysis, and the R/, tests/, and scripts/ directories fill in as the code in the document matures.
The doctrine’s reproducibility payoff is that the document is sealed from the first day and stays sealed. There is never a phase in which results live in the prose by having been copied there. The number in the paragraph was computed by the chunk above it on the very first render, and on every render since. The drift that opened this chapter has no moment at which to enter.
We now assemble the pieces into a concrete report.Rmd, as a health scientist beginning a cohort analysis would. On the first day, before any data are analyzed, the author creates the report and writes its header. A representative YAML header, shown here as a static, unrendered block, declares the title, the authorship, the output formats, and the bibliography:
---
title: 'Bill morphology across three penguin species'
author:
  - name: A. Analyst
    affiliation: Department of Epidemiology
date: 'November 08, 2026'
output:
  bookdown::pdf_document2:
    number_sections: true
    keep_tex: true
  bookdown::html_document2:
    toc: true
bibliography: references.bib
---
Two features of this header repay attention. The output field names two formats, a PDF built through LaTeX for submission and an HTML version for reading on a screen. The project that renders the former needs the publishing profile and its baked-in LaTeX distribution, while the latter needs neither. The date field is itself a small literate device: it holds an inline R expression that inserts the render date, so the header cannot claim a date the render did not have. The provenance footer discussed below is not declared in this header at all; it is applied by the render tooling (make docker-render, by way of tools/stamp-render.R).
Below the header the author writes a setup chunk that fixes the chunk defaults and loads the packages the document uses. Each package is named with an explicit library() call so that renv can discover them and no package is installed at render time:
knitr::opts_chunk$set(
  echo = FALSE,
  message = FALSE,
  warning = FALSE,
  fig.path = '../figures/'
)
library(dplyr)
library(ggplot2)
From here the write-as-you-go doctrine takes over. The author writes the introduction as prose and adds a data-summary chunk. Then come the modeling chunk that produces the analysis and the figure. The figure chunk is exactly the sealed fig-simpson chunk demonstrated earlier in this chapter, which computes its result at build time and carries its synthetic inputs with it. Each number the introduction and discussion cite is inserted by an inline expression that reads the computed object, never typed by hand. Rendering the document inside the container, with make docker-render or its equivalent, executes every chunk in a fresh session, regenerates every figure, and produces the PDF and HTML, each carrying the render’s provenance footer.
The result is a document that is sealed by construction. To convince ourselves that the seal holds, and does not merely appear to hold on the author’s machine, we render it from a fresh clone of the repository inside the pinned environment (habit 6). If it renders there, with no file missing and no package installed on the fly, the seal is real. If it fails, one of the landmines cataloged above has been stepped on, and the failure names which.
The same discipline applies directly to this book’s own running cohort. The chunk below loads and cleans the extract and computes two numbers the way every sealed document should, as objects a sentence can cite rather than as values copied from a console.
The cleaned cohort holds 337 records, of which 9.5 percent carry no recorded outcome. Both numbers are inline expressions reading cohort, not literals typed after a console check. A later edit to clean_cohort(), or to the raw extract, therefore changes this paragraph on the next render instead of leaving it to drift the way the orientation’s opening story describes. Nothing about this passage pins a package or an environment; it is the seal, and only the seal, demonstrated on the book’s own data.
A language model is a capable assistant for literate documents, and a treacherous one, because its fluency in producing chunks that run on the author’s machine is exactly the fluency that plants landmines. Three exchanges illustrate the pattern of use and the verification the analyst must supply.
One rule comes first (habit 3). Never paste or upload protected health information, identifiable records, or data held under a data use agreement, nor outputs derived from them, into a model or a coding agent unless three conditions all hold. The institution has approved that endpoint for that class of data. The IRB protocol and the consent permit the processing. The data use agreement, or the provider’s terms, permits it. If any of the three is unclear, the answer is no.
The third condition is the one most often missed. Institutional approval of a tool does not override the terms under which a data provider released the data. NIH, for example, treats sharing controlled-access data through prompts with public generative AI tools, which it glosses as third-party tools, as a breach of the data use certification. It treats a model trained on such data as a data derivative, to be shared only with other approved users and not kept after the project closes (National Institutes of Health, 2025).
Describe the structure instead: the column names and types, or a small synthetic example generated from the data dictionary, never edited from real rows. A coding agent sees whatever files are in its working tree, so run it in a checkout or container where the real data is not mounted.
An agent also acts, so confine it to a branch and keep merges, pushes, and deposits for yourself (Section 2.10.1).
A literate document mixes code with data and results, so it is easy to paste too much. The derived outputs the rule covers include a rendered table of small cells, and a coding agent asked to render the document reads the data it renders.
Prompt. ‘Write a knitr chunk that loads dplyr and survival and reads the CSV at analysis/data/raw_data/cohort_raw.csv, which has columns mrn (character), enroll_date (character, in two date formats), hba1c and bmi (numeric), and incident_dm (integer, 0 or 1, with missing values).’
Watch for. Check for convenience chosen over the seal: a pacman::p_load(...) call, an install.packages() call, or a library(pacman) line. Check also that the data are read from the path given, not from an invented absolute path such as /Users/you/data/cohort.csv or from a path outside the project.
Verification. Insist on explicit library() calls, one per package, with no installation on the render path, and a relative path to a committed file under the compendium. Then apply the decisive test: render the chunk from a fresh clone inside the container. A chunk that survives that test is sealed; a chunk that only ran in the author’s console is not, whatever the model asserted.
Prompt. ‘My PDF render fails with a LaTeX error but the HTML render works. Fix it.’
Watch for. A model may propose to install a LaTeX package at render time, or to add a tinytex::tlmgr_install() call inside a chunk. Either converts an environment problem into a render-time landmine and makes the document depend on network access and repository state.
Verification. The correct locus of the fix is the environment, not the document. Confirm that the failure is a missing LaTeX toolchain, and provision it by building on the publishing profile so that LaTeX is baked into the image, not installed as the document renders. Verify that the PDF then renders in the container with nothing installed on the fly.
A better prompt. ‘My Quarto document renders to HTML, but the PDF render fails; the log is attached, with paths replaced by placeholders. The build runs in a container from the attached Dockerfile, and nothing may be installed during the render. Identify the missing LaTeX component from the log, propose the Dockerfile change that provides it, and name the command and the log line that will confirm the fix.’
Prompt. ‘Find the hidden state in this document.’
Watch for. Check whether the answer rests on reading the source alone. Hidden state belongs to the session in which the chunks run. A reading can miss an object created in the console, an option set in .Rprofile, or a chunk that works only because a cached predecessor was skipped, and it can flag chunks that are in fact self-contained.
Verification. Test each item by execution. Delete _freeze/ and any cache directory, so that the skipped chunks of Section 9.8 run too, and render the document in a fresh session inside the container. Then run each flagged chunk alone in a new R session. A chunk that fails alone depends on state that something earlier supplied; a chunk that passes does not, whatever the model reported.
A literate document carries the same disclosure obligation as the rest of the paper. A render’s seal attests that the code ran and the prose agrees with it, not who or what drafted either. Record any model use in drafting a chunk, a caption, or a paragraph with the template and the LLM-USE.md record of Section 2.10.2. A model is also not a versioned dependency the way a package is: a provider can retire or update an identifier, and one unchanged version need not return the same text twice. The reproducibility conclusion follows. Text a model drafted is reproducible only as the committed file, never by asking again, and a model whose output feeds the analysis is a dependency in its own right (Section 10.12).
Take an existing .Rmd or .qmd document of your own in which at least one reported number was typed into the prose by hand. Replace that number with an inline R expression that computes it from the data, render the document, and confirm the value is unchanged. Then edit the data slightly, re-render, and observe the number update in the prose. Describe what would have happened to the hand-typed number under the same edit.
Write a short knitr or Quarto chunk that generates synthetic data with set.seed() and produces a figure, as the fig-simpson chunk in this chapter does. Render it twice and confirm the figure is identical. Then remove the set.seed() call, render twice more, and explain in terms of this chapter why the figure now differs between renders and what that implies for the seal.
Deliberately plant each of the five landmines from this chapter, one at a time, in a copy of a working document. The five are an install.packages() call, a pacman::p_load() call, an absolute host path, a chunk that depends on hidden state from an earlier chunk, and a read of an uncommitted file. For each, predict whether the document will still render on your own machine, then test the prediction by rendering from a fresh clone in a clean environment.
Locate a document in your work that renders to PDF, and determine whether the LaTeX toolchain it requires is pinned in an environment or assumed present on the host. If it is assumed present, describe the steps by which you would move it into the publishing profile, and state which reproducibility level the move would raise the project to.
Render a PDF from a literate document twice, minutes apart, and compare the two files byte for byte (for instance with a checksum). Confirm that they differ, inspect the metadata to identify what differs, and explain why hashing the rendered document would be the wrong basis for verification. Then describe what should be compared instead, and how.
For each of the five archetypes named in this chapter, the manuscript, the blog, the data analysis, the R package, and the simulation study, write one or two sentences stating what the literate document renders in that archetype, if anything, and how heavily the reproducibility weight rests on the render as opposed to elsewhere.
On the running cohort compendium, run clean_cohort(load_cohort('analysis/data/raw_data/cohort_raw.csv')) and write a one-sentence, inline-sealed report of the cleaned row count and the percentage of rows missing an outcome, in the style of ‘The cohort, continued’ above. Report the two specific numbers a grading script could check without rendering anything: nrow(cohort) and the percentage missing incident_dm, rounded to one decimal place.
This exercise returns to the dependency-pinning discipline of Chapter 6 (Chapter 6). The fig-simpson chunk in this chapter loads dplyr, tibble, and ggplot2 with explicit library() calls. Run renv::dependencies() on this chapter’s own .qmd file, as Chapter 6’s own cohort exercise runs it on R/cohort.R, and report which of those three packages the scan finds referenced. Then write a scratch .R file whose only line is pacman::p_load(dplyr, tibble, ggplot2), scan it the same way, and report what the scan finds. Explain what the result implies for the pacman landmine, and for any claim about a scanner’s coverage that has not been tested.
Attempt an exercise before expanding its solution. Most of this chapter’s exercises are performed on a document of the reader’s own, so their outputs vary; the boxes record what should happen and why.
| Command or rule | What it does |
|---|---|
library(pkg), one per package |
Names a dependency in the form every scanner recognizes and loads without installing; prefer it to pacman::p_load(), which installs at render time. |
| An inline R expression in prose | Seals a number in prose to the code that computes it. |
knitr::opts_chunk$set(...) |
Sets chunk defaults, echo, message, warning, fig.path, once near the top. |
SOURCE_DATE_EPOCH |
Fixes the embedded build timestamp, so two renders agree on that one field. |
make docker-render |
Renders inside the pinned container and stamps the provenance footer (habit 6). |
| Five landmines | Installing at render time; pacman::p_load(); an absolute host path; hidden cross-chunk state; reading an uncommitted file. |
| Rule of thumb | A sealed render binds prose to code; it pins no package, no environment, and proves nothing correct. |
| Rule of thumb | Compare the computational outputs with a recorded baseline within a stated tolerance (habit 5), not the rendered PDF or HTML; the render’s bytes are not the object of record. |
| Habit 6 | Rebuild from clean, on a machine that is not yours, to test whether the seal actually holds. |
| Habit 7 | Write the honest level down; ‘it renders’ is a claim about the seal, not about L1, L2, or L3. |
freeze: auto |
Re-executes a document only when its source changes; data, package, and R changes do not trigger it (Section 9.8) |
The foundational statement of literate programming is Knuth (1984), which repays reading in the original for its inversion of the usual priority of code over explanation, even though its concrete apparatus is now of historical interest. The reproducibility argument this chapter takes as its keystone is Buckheit & Donoho (1995). Their paraphrase of Claerbout, that the article is advertising and the code and instructions are the scholarship, is the sentence this book takes as its keystone, and the one worth committing to memory. The earlier formulation in Claerbout & Karrenbach (1992) and the signal-processing lineage surveyed by Vandewalle et al. (2009) give the argument its original setting.
On the R realizations, Xie (2015) is the definitive treatment of knitr by its author, and Xie et al. (2018) documents R Markdown and its pandoc-based toolchain. Allaire et al. (2024) introduces Quarto and is the natural starting point for a reader beginning today. The compendium framing that binds the literate document to the rest of the project is Gentleman & Temple Lang (2007), who first proposed the compendium as an executable document, and Marwick et al. (2018), whose rrtools operationalizes it around a report.Rmd. For the practical habits, Sandve et al. (2013) and Wilson et al. (2017) both stress recording exactly how each figure was produced, which is the sealed render stated as a rule of conduct. The determinism questions touched on here connect to the verification machinery of Chapter 12. In the wider setting of reproducible builds, they also connect to a substantial body of systems literature, beyond the scope of this book, that a reader pursuing byte-level reproduction of documents will want to consult.